
I stopped designing everything in Figma
For years, almost all of my design work lived in Figma. I explored ideas, built components, connected screens into prototypes, polished interactions, and handed everything to developers. It worked. It still does. But at some point I realized I was spending a lot of time designing an approximation of the thing I actually wanted to design. A website isn't a Figma frame. A product isn't a collection of screens. Real interfaces have viewports. Text wraps. Content changes. Layouts break. Things scroll. Animations have timing and weight. Sometimes something that looks perfect in Figma simply feels wrong in a browser. So I started moving into the browser much earlier. At first, I just wanted to test things that were annoying to prototype in Figma: scroll behavior, responsive layouts, menu transitions, specific interactions. Instead of spending an hour building a prototype, I'd describe what I wanted to an AI coding agent and make a simple HTML version. HTML. CSS. JavaScript. Open. Click. Feel. I could resize the window, use real content, see what happens when a title wraps to three lines, break something, fix it, and test again. The feedback loop became much shorter. I still use Figma every day. It's excellent for visual exploration, systems, components, information architecture, and comparing ideas side by side. I just stopped expecting every design decision to be finalized there. Sometimes I make enough in Figma to understand the direction and then move into the browser. Not because that's where a developer will eventually implement my design. Because that's where I continue designing it. The browser immediately exposes things a perfect 1440px frame doesn't: awkward wrapping, viewport constraints, dropdowns opening in bad places, sticky elements covering content, strange keyboard behavior. I want to discover those problems before I call the design finished, not after handoff. I'm a designer, not a frontend engineer. A few years ago that created a hard boundary. I could describe an interaction or prototype an approximation, but someone else eventually had to build it before I could really experience it. AI coding tools softened that boundary. Now I can describe behavior, get something working, open it and react: Too slow. Too much movement. This should push the content instead. Mobile feels terrible. Change it. Then test again. It's the same iterative process I used to have with Figma frames, except now I'm evaluating behavior instead of screenshots. My prompts changed too. Instead of: Make this button smaller. I try to explain the decision: This is a secondary action. It competes with the primary CTA. Reduce its visual weight while keeping a comfortable hit area. The prompt becomes a small design specification. Once I started working this way regularly, I noticed another problem. I'd open a prototype and see ten tiny issues, then spend time explaining exactly which DOM element I meant. In the pricing section, second card, the button below the feature list... The element was literally in front of me. I tried annotation tools for AI workflows, but eventually built my own small one: Gnom. I click an element, leave a note, and the agent gets structured context about what I'm pointing at. Gnom wasn't the reason my workflow changed. It was a consequence of it. The tool came from the workflow. This became much more useful on real product work. On Remedico, a dental practice management platform, I worked with calendars, dental charts, treatment plans, patient records, communication tools, permissions, AI features, and complex clinical workflows. A static screen tells only part of that story. A dental chart can look beautiful in a presentation. That doesn't tell you whether selecting several teeth, changing a diagnosis, adding a treatment, undoing an action, and switching patients actually feels good. I became more interested in testing the system, not the screen. In some flows, the handoff changed from: Here's how it should work. to: Here's how it works. Let's make it production-ready. That's a very different conversation. Scrollcast started from a small personal annoyance: I wanted better-looking recordings of websites and product interfaces. So I built, used, changed, and rebuilt it. A little design. A little code. Use it. Notice what's annoying. Change it. At some point it became difficult to say where design ended and development started. For this kind of work, I'm not sure that distinction matters much. The product itself became the design file. This isn't a "Figma is dead" article. Figma is still faster for many things: exploring ten layouts, defining visual language, working on a design system, or communicating an early concept. The change is simpler: I stopped expecting one tool to contain the entire design process. Sometimes it's: Idea → Figma → Browser → Figma → Browser Sometimes: Idea → Browser The tool matters less than how quickly I can answer: Does this actually work? My old process looked neat: Research → Wireframes → UI → Prototype → Handoff → Implementation → QA Now it's closer to: Idea → Figma → Code → Test → Change → Code → Test → Ship Messier, but closer to how products actually evolve. AI made this workflow possible for me, but AI isn't the interesting part. The interesting part is how much shorter the distance has become between making a design decision and experiencing its consequence. "What if this wasn't a modal?" Five minutes later, I can use the alternative. "What happens with 40 items?" I can actually scroll through 40 items. "This animation should feel heavier." I can test three versions instead of documenting the idea. That's the change I care about. Not generating more UI. Getting feedback from the actual medium sooner. I still open Figma every day. I just open the browser next to it. And increasingly, that's where the interesting part begins.
Clients are terrible at briefs — so I built Tinder for design
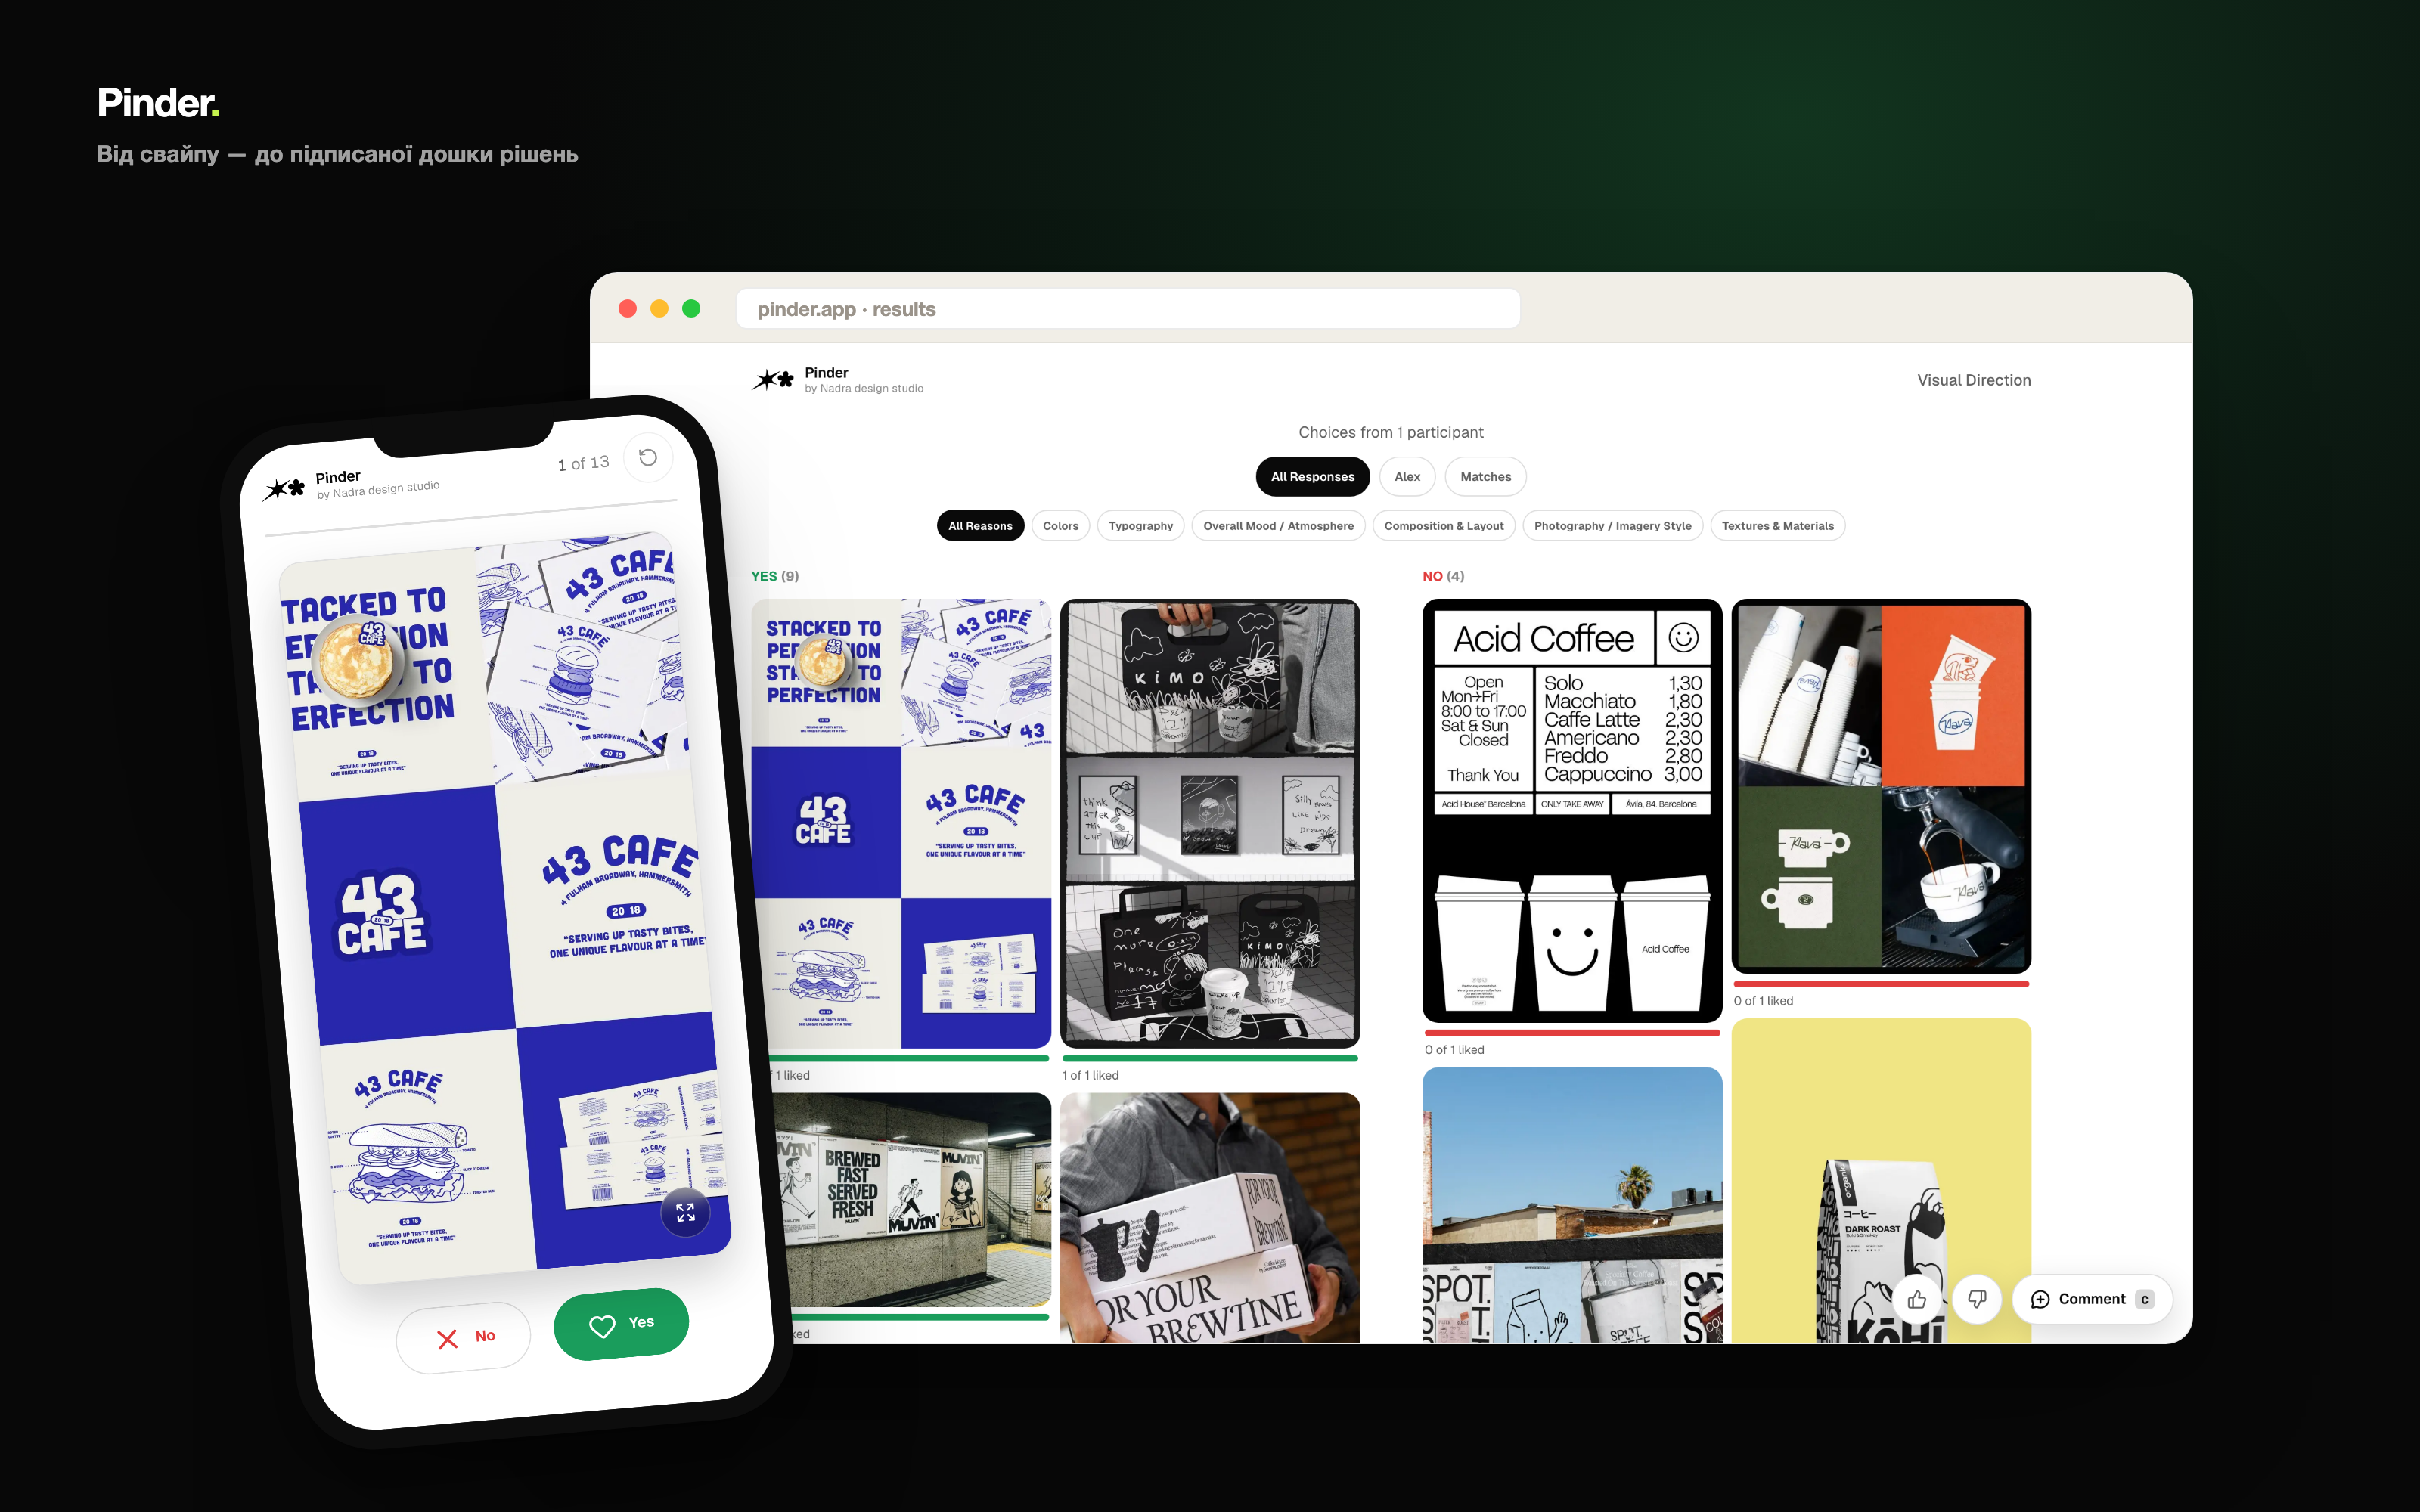
Every project at the studio starts the same way. The client says something like: "we want it modern, but with character," "premium, but not boring," "I'll know it when I see it." And then comes the stage I quietly call the guessing game: we prepare three directions, export them, lovingly name the files finalv2, and wait. 47 revisions later everyone's exhausted, and nothing's approved. The problem isn't that the client "doesn't know what they want." The problem is that a brief in words is a bad language for visual taste. People are terrible at describing aesthetics in text. But they're brilliant at instantly saying "oh, that — yes" or "ugh, no" the moment they see a specific picture. That's how Pinder was born — a swipe-to-decide tool for visual taste. Instead of describing taste in words, the client simply flips through a set of references one by one, Tinder-style — yes or no. And the studio gets, not a contradictory brief, but a clean board of shared preferences. Pinterest × Tinder × Finder = Pinder. One evening I caught myself thinking: we already have the perfect interface for this. People swipe in Tinder every day and make gut decisions in half a second. What if choosing a visual direction felt as easy as meeting someone? The key is focus. When there's one image filling the screen instead of a moodboard of forty, you react on instinct, not "diplomatically." There's no room for "well, it depends." There's only the first impression — and that's exactly what you need. The client opens a private link, enters their name — and starts flipping. One reference at a time. Right or the green button — like; left or red — no. It works with swipes, buttons and arrow keys; there's undo if you change your mind; progress restores if you close the tab. Saying "I like it" isn't enough. After every Yes, Pinder asks what exactly worked: colour, typography, mood, composition, photography, texture. It turns intuition into data. By the end of a session you see not just which references won, but why — and that's already a shared language for talking about direction. The step is optional, and the studio edits the list of reasons per session. When everyone's done swiping — the results board appears. Two columns: Yes on the left, No on the right. You can filter by each participant, view only "Matches" where everyone agreed, filter by reason, count votes. Click for a lightbox, and leave Figma-style comments and 👍 / 👎 stickers over the images. That's the "signed board": instead of "I thought you said you liked minimalism" — concrete, recorded decisions everyone can see. On the studio side, everything lives in a password-protected admin. You create a session, drag in images (drag-and-drop, reorder, delete) — or pull them straight from a Pinterest board. You edit the list of reasons, hit "Start" — and instantly get a link for the client. Plus a public results link with no login, a "Finish" button, and a danger zone for restarting or deleting. Visually the tool is deliberately quiet: cream paper, graphite text, and green / red only as a Yes / No signal — no extra brand colour, so nothing gets in the way of reacting to the references themselves. Pinder is built on Next.js (App Router) with TypeScript and Tailwind, animated with Motion. Data lives in Supabase (Postgres + Storage); without keys the app falls back to in-memory storage, so the demo works offline too. Hosting is Vercel with auto-deploy from git. Large photos are compressed right in the browser so they don't hit limits. The best thing about Pinder is that the "guessing game" disappears before the first mockup. In 5 minutes of swiping a client gives more signal than in an hour-long meeting. The conversation about direction starts not from a blank page, but from a shared board where you can already see what resonates — and, just as importantly, what definitely doesn't. It also turned out to be simply pleasant. People have exactly zero patience for briefs — but they'll swipe for as long as you like. Sometimes the best solution isn't writing another brief — it's letting someone swipe.
I got tired of janky screen recordings — so I built Scrollcast
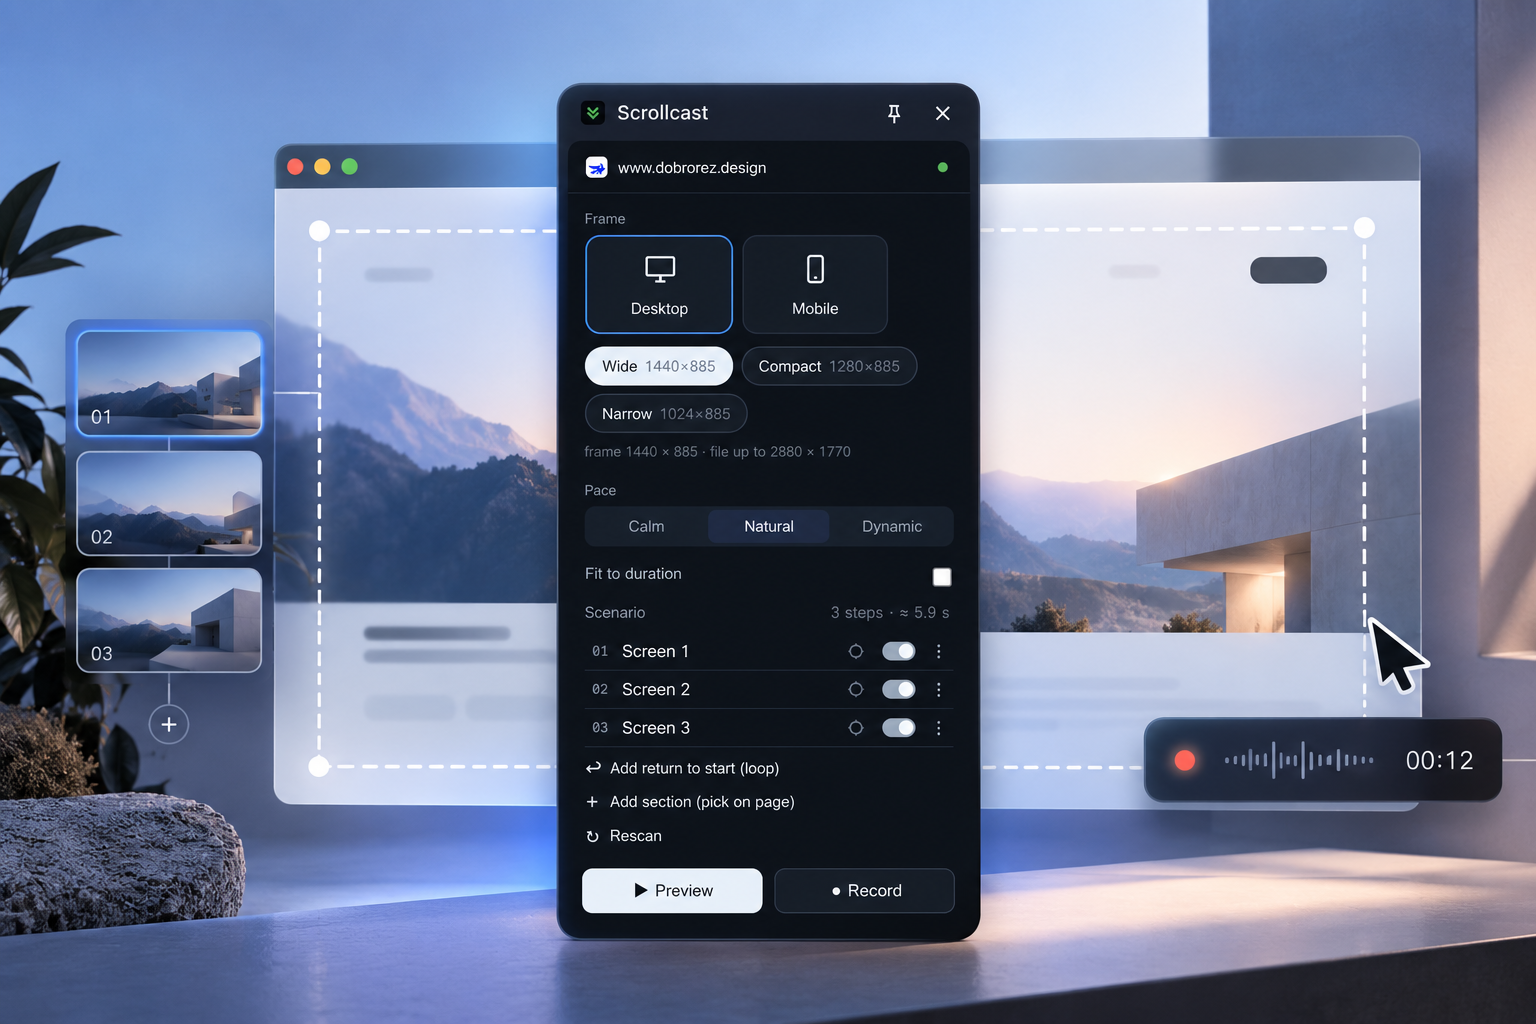
Every landing page needs a video. A preview for a case study, a clip for stories, a demo of a template for sale. And every time it's the same story: you record the scroll with the system recorder — and out comes jank. The scroll stutters, frames drop, and instead of "wow, so smooth" you get something you're embarrassed to show. Smoothness is half a designer's job. So I built a tool that guarantees it. Scrollcast is a browser extension. Open a site → one button → get a smooth scroll video. Not a screen recording, but a synthetic scroll, computed section by section: even acceleration, soft braking, pauses where the eye should linger. Scrollcast's main decision — it hands you a clean plate: no browser chrome, no background, no shadows. Just a smooth scroll of the site on a clean frame. Why? Because styling is your territory. The device mockup, background, shadows, effects — you'll make those in Figma or After Effects exactly the way you see them. Scrollcast doesn't impose a style — it gives you a perfectly smooth base to do anything with. - Auto-scenario. The scan finds the page's sections and builds the scroll itself — showing every block, losing nothing. - Pace, not budget. You pick the character of the motion — Calm, Natural, Dynamic — and the duration adapts. No sections silently disappearing. - Position fine-tuning. Didn't land the frame on the right spot in a section? Click, drag on the page, lock it in. - Desktop and mobile frames. 1440/1280/1024 and iPhone/Android — pick a size, hit record. - Clean MP4 (H.264), 2× on Retina. Scrollcast was built iteratively and honestly — with an automated bench that runs the scan, scenario and recording itself, catching regressions. Every frame, every bit of smoothness — measured, not promised. Right now Scrollcast is in active development — final details before launch on the Chrome Web Store. If you build landings on Framer / Webflow and you're also sick of janky previews — stay tuned, it's coming soon.
How I built my own annotator for AI prototypes
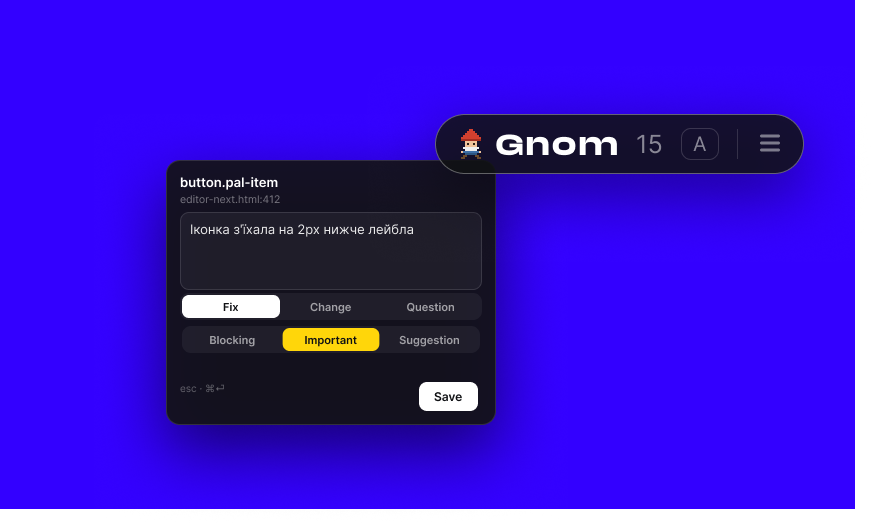
Lately I've been designing more and more directly in the browser. Not in Figma, but in a live HTML prototype: I open the page, click through the interactions, see what feels wrong, and immediately ask an agent to update the code. At first the workflow was very simple. I'd just send commands like “reduce this spacing,” “make this button shorter,” “rework this section.” That works fine while there are only a few changes. But once the prototype gets more complex, a familiar problem appears: the agent doesn't always understand which exact element the comment refers to. “This block” is obvious to me, but not necessarily to the model. Then I found Agentation, an annotation tool for working with AI agents. I really liked the idea: click directly on an element in the browser, leave a comment, and the agent gets the context without extra explanation. It made the workflow much faster. But for my use case, two problems remained. The first was accuracy — sometimes the annotation would resolve to a different element than the one I actually meant. The second was tracking: once I had 10, 20 or 30 changes, it became hard to manage them as actual tasks — what the agent had already seen, what was fixed, what was blocked, and what I no longer wanted to change. So I decided to build my own tool around the way I work. I called it Gnom. Gnom works as a lightweight annotation layer on top of an HTML prototype. I turn it on, click the element I want to change, and leave a comment. But instead of keeping annotations as a loose collection of comments, every change goes into a single table. For each note I can see the element and its location in the code, the comment, the type of change, its priority, its status, and its current progress. In practice it becomes a small backlog wired directly to the prototype. Another important difference is that I try to anchor the annotation not only to the element's position on screen, but also to the actual HTML fragment behind it. That makes the connection between what I point at in the browser and what the agent should change in the code much more reliable. The workflow now looks like this: I review the prototype, leave all the annotations, review them in the table, the agent prepares a plan — and only then does it start making changes. Fewer conversations like “no, not that div.” Fewer lost comments. And it's much easier to review a large prototype in one pass. There's also a tiny pixel gnome living in the interface. When annotation mode is off, he sleeps. When it's active, he runs. It has almost no functional value — but I'm increasingly convinced that vibe coding can be both efficient and fun. So the gnome stays. I've also made the tool publicly available, so you can drop it into your own HTML project and use it in your own workflow.